


 下載報告
 聯絡我們
AI Infra市場快訊 - 2026年11月12日

發佈日期
2026-11-12

更新頻率
每二周

報告格式
隨著AI算力擴展,傳統銅線因物理距離受限,促使機櫃內銅纜結合跨櫃光學的混合架構率先普及。推論需求進一步推升互連網路發展。儘管面臨佈建挑戰,先進光學技術將逐步放量,成為突破傳輸瓶頸的關鍵。
重點摘要
- 突破銅線極限:AI算力跨櫃擴展使傳統銅線面臨物理傳輸距離限制,跨櫃光學互連成為必然趨勢。
- 混合架構為首選:考量總體成本與延遲要求,推論系統將優先採用「機櫃內銅纜、跨櫃光學」的混合設計。
- 先進光學漸普及:近封裝與共同封裝光學將逐步進入量產階段以降低功耗,但產業仍需克服光纖暴增的管理與實體佈建挑戰。
目錄
- Executive Summary
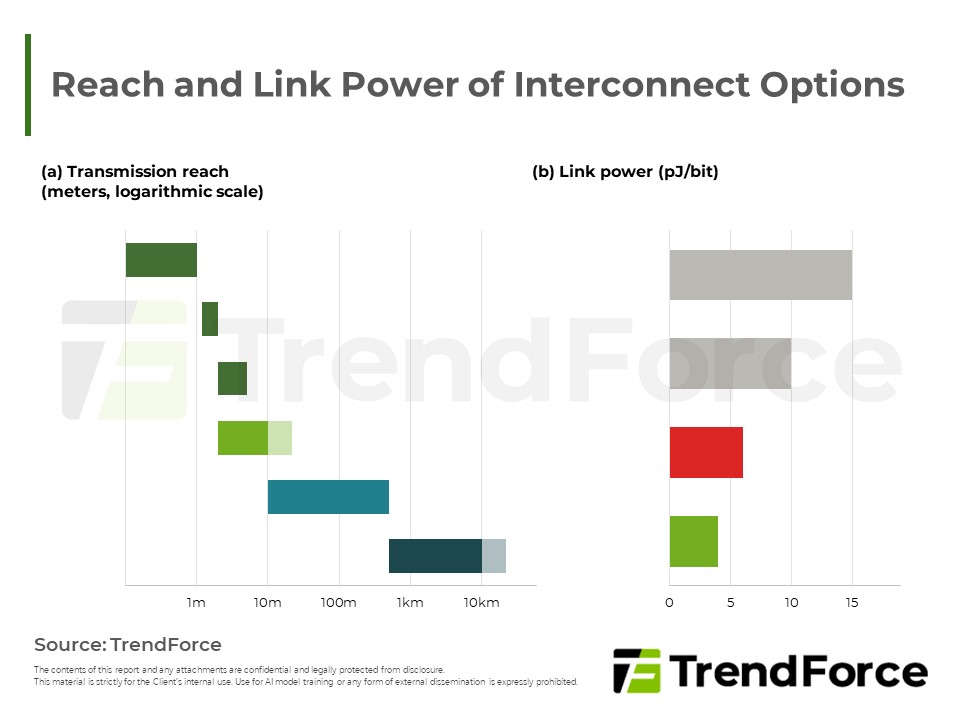
- Figure-1: Reach and Link Power of Interconnect Options
- Key Findings and Takeaways
- Figure-2: Meta Rack Platforms and Accelerators per Rack
- Table-1: Scale-Up Domain Scale: Vendor Descriptions
- Figure-3: Hybrid Copper/Optical vs. Full Optical Scale-up Pods
- Figure-4: Peer-to-peer Serving Architecture with PDC Disaggregation on CloudMatrix384
- Figure-5: TPU 8i Hierarchical Boardfly Topology
- Figure-6: Maximum Seven-hop Network Diameter via OCS on TPU 8i Pod
- Figure-7: Maia 200 Unified Ethernet Hierarchy
- Table-2: Scale-Up Domains and Deployment Scales for Training vs. Inference
- Figure-8: Interconnects for Training vs. Inference Clusters
- Figure-9: OpenAI Jalapeño Two-level Scale-up Topology
- Table-3: Specifications of the Jalapeño Two-Tier Scale-Up Architecture
- Figure-10: UB Switch System in CloudMatrix384
- Table-4: Cross-Rack Scale-Up Links and Optical Usage Across Inference Platforms
- Table-5: Reach and Power Consumption of Copper Interconnects (200G / 400G)
- Figure-11: Limitations of Passive Copper (DAC) at 200G
- Figure-12: Total Link Power and Reach Comparison, 200G
- Figure-13: Fibers and Installation Hours per Compute Rack, 2026-2028+
- Table-6: Comparison of Fibers per Rack: NVIDIA, Broadcom, and Meta
<報告頁數:13>
領域: AI伺服器/資料中心


AI Infra Bulletin相關報告

下載報告
TWD
